Solving the DMS Validation Data Gap: Synthetic Data to Master Rare Driver Behaviors
Solving the DMS Validation Data Gap Synthetic Data to Master Rare Driver Behaviors
SHARE

Table of Contents

Table of Contents

The DMS Accuracy Paradox

Modern driver monitoring systems (DMS) have achieved impressive accuracy rates, often exceeding 95% in detecting common distractions like yawning, phone use, or prolonged eye closure. However, this high benchmark performance masks a critical vulnerability: the DMS validation data gap. This is the chasm between laboratory performance and real-world safety, caused by the “long tail” of driver behavior—the rare, high-risk events that are nearly impossible to capture with real-world data.

This “DMS Accuracy Paradox” means a system can excel in testing yet fail on the road when faced with a brief micro-sleep, a moment of subtle cognitive distraction, or an edge case in child presence detection. While statistically infrequent, these failures carry disproportionate consequences for safety and brand integrity.

In Europe, driver distraction contributes to roughly 20–30% of crashes, highlighting the importance of capturing these rare behaviors. The regulatory landscape is now formalizing this challenge; with Euro NCAP 2026 and UNECE regulations expanding in-cabin monitoring requirements to include drowsiness, distraction, and child presence, the goalposts have moved. The new mandate is not just high accuracy, but comprehensive robustness.

OEMs need better data: controlled, repeatable, and physics-accurate.

This article explores how overcoming the DMS validation gap requires a new approach to data. We will examine how physics-based synthetic data provides the controlled, scalable, and semantically precise solution needed to engineer and validate DMS performance against these critical, rare scenarios, finally closing the gap between laboratory metrics and real-world safety.

The “Long Tail” Problem: Why Your DMS Is Only as Good as Its Rarest Test Case

In machine learning, the “long tail” refers to the vast set of rare events that are individually infrequent but collectively critical. For Driver Monitoring Systems (DMS), this is the domain of high-risk, low-frequency behaviors that are notoriously absent from real-world datasets. While a DMS might excel at detecting common distractions, its true safety value, and its ultimate regulatory validation, is determined by its performance on these rare but catastrophic scenarios.

Concrete Examples: Where State-of-the-Art DMS Stumble

Low-frequency driver and occupant states that carry disproportionate risk include:

Category

Examples

Challenge

Micro-sleeps

Eyelid flutter vs. 2–3 second closure

Difficult to capture naturally; ethically impossible to induce in real drivers

Subtle Distractions

Cognitive disengagement, mirror checks, gestures

Ambiguous, transient cues rarely labeled consistently

Child Presence Edge Cases

Partially visible children, occlusion under blankets, reflections on buckles

Safety-critical, ethically and practically impossible to capture in real-world data

The long tail manifests in several safety-critical categories where current data collection methods fall short:

  • Micro-sleeps: The critical distinction between a long blink and a 2-3 second eyelid flutter is a matter of lane departure. Capturing thousands of natural, progressive micro-sleeps across diverse drivers, varied lighting, and fatigue levels is logistically infeasible and ethically prohibitive.

  • Subtle distractions: Distraction isn’t always a phone in hand. It can be cognitive “off-loading”, a driver staring blankly through the windshield, mentally disengaged. These ambiguous, transient states are nearly impossible to consistently capture and label from real-world video, creating a significant gap in understanding attentional loss.

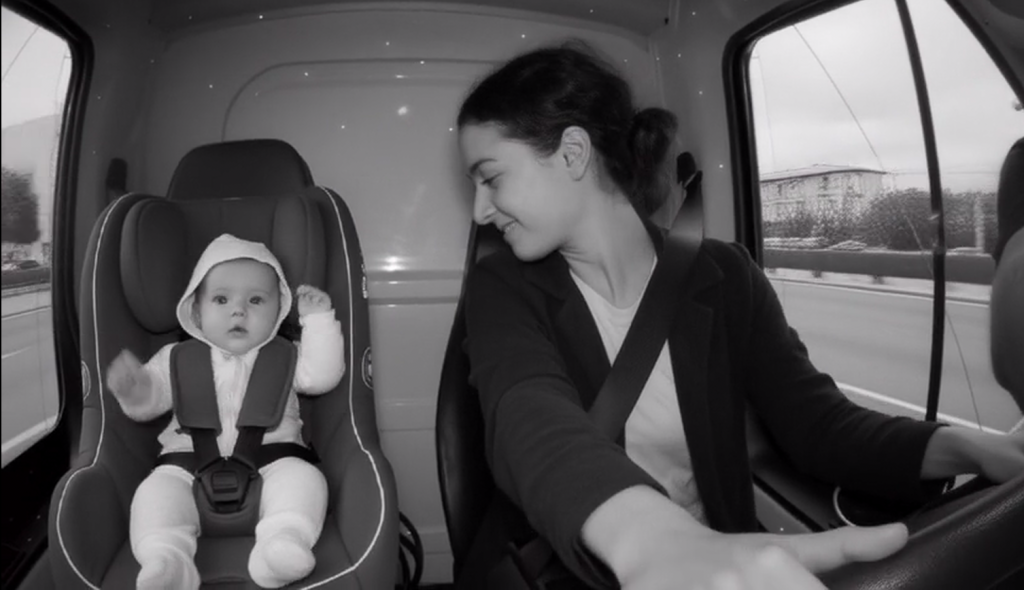
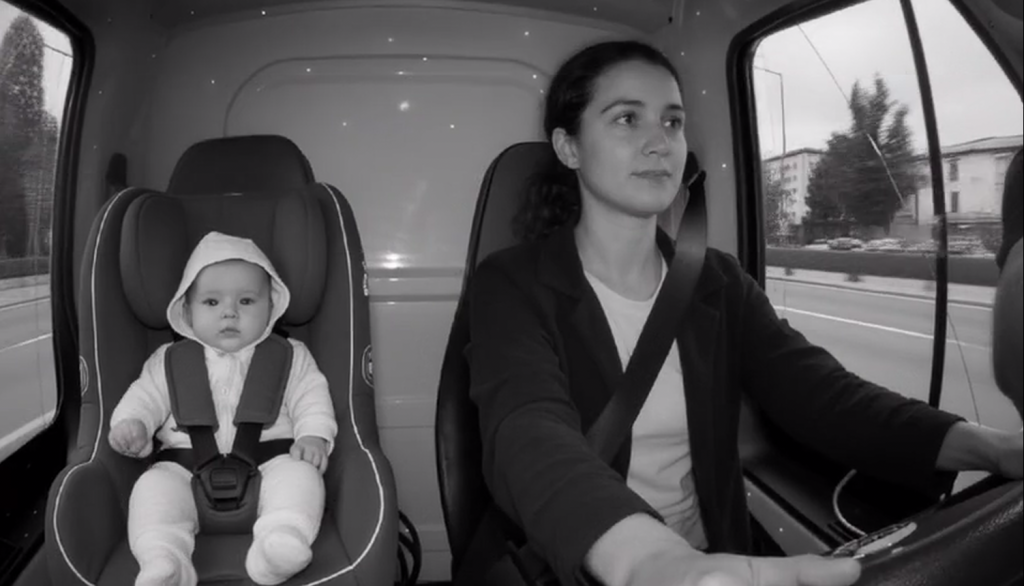
  • Child Presence Detection (CPD) edge cases: In CPD scenarios, the tolerance for error is zero. The system must identify a child partially obscured by a blanket, completely hidden behind a seat, or visible only as a reflection on a buckle. Artificially creating these scenarios for data collection with real children is both unsafe and unethical, leaving a dangerous void in training data, practically impossible.
The Insurmountable Hurdles of Real-World Data Collection

The common thread across all long-tail scenarios is the fundamental impossibility of capturing them at scale with real-world data. The challenges are not just logistical, but foundational:

  • Ethical & Safety Barriers: You cannot ethically induce drowsiness in test drivers or place children in potentially hazardous positions for the sake of data.

  • Combinatorial Explosion: Each scenario depends on a complex interplay of variables, driver age, posture, seat position, lighting (glare, IR reflectance), and behavioral context. Systematically replicating all these combinations in the physical world is prohibitively expensive and time-consuming.

  • Annotation Ambiguity: Even when rare events are captured, how do you consistently and accurately label a “subtle cognitive distraction”? Human annotators often disagree, leading to noisy, unreliable ground truth.

This creates the core paradox of DMS development: the most safety-critical data is, by its very nature, the most inaccessible. Relying solely on real-world data inevitably leaves a dangerous gap between benchmark performance and real-world robustness.

The Real-World Data Bottleneck: Why Physical Collection Fails the Long Tail

The long tail defines the frontier of DMS safety, yet it is a frontier that real-world data collection is fundamentally unequipped to explore. Relying solely on real-world data creates a bottleneck defined by four insurmountable constraints: scarcity, cost, ambiguity, and privacy. This makes validating robust DMS a major challenge, especially as Euro NCAP 2026 raises expectations for system performance.

Scarcity: You Can’t Schedule a Micro-Sleep

The very nature of long-tail events makes them elusive. Micro-sleeps, subtle cognitive distractions, and specific child presence edge cases are, by definition, rare and unpredictable. Systematically capturing a statistically significant volume of these events across the required variations of driver demographics, cabin configurations, and environmental conditions is a logistical impossibility. You cannot command a test driver to have a safety-critical lapse on cue. This scarcity creates a permanent coverage gap in datasets, leaving models untested against the very scenarios they are designed to prevent.

Cost: The Exorbitant Price of Rarity

Chasing rarity is prohibitively expensive. Establishing a data collection pipeline for in-cabin monitoring requires a fleet of instrumented vehicles, calibrated sensor suites (e.g., RGB, IR, NIR, Radar), and controlled test facilities. The cost multiplies exponentially when the goal is to capture thousands of hours of driving to find a few hundred critical seconds of rare events. Furthermore, the subsequent manual annotation of these complex behaviors adds a massive, ongoing expense, making comprehensive long-tail data collection a venture with a diminishing and untenable return on investment.

Annotation Ambiguity: The Subjectivity of Subtlety

Even when a rare event is captured, defining it is often subjective. How does one consistently label the precise moment a “blink” becomes a “micro-sleep”? Or quantify “cognitive distraction” from a driver’s vacant expression? Studies have shown inter-annotator disagreement rates of 12-15% in DMS behavioral datasets. This “label noise” directly injects uncertainty into model training, limiting the maximum achievable performance and making it difficult to validate systems against stringent safety benchmarks.

Privacy: Data Collection is Sensitive

In-cabin video is a minefield of personal data, encompassing biometric identifiers (facial features, gaze) and sensitive behaviors. This triggers strict global regulations like Europe’s GDPR, which mandates consent and anonymization, and UNECE R155, which covers cybersecurity. Collecting, storing, and processing this data at the scale required for the long tail introduces massive legal and reputational risk. The very act of comprehensive data collection becomes a compliance nightmare.

Engineering the Impossible: Generating the Long Tail with Synthetic Data

If real-world data collection is defined by its constraints, synthetic data generation is defined by its freedom. By moving from the physical to the virtual domain, we can engineer the very scenarios that are impossible to capture, with precision, scale, and control that transcends traditional methods. This is not merely supplementing real-world data; it is pioneering a new paradigm for DMS validation and future assessment.

The Core Capabilities of a Synthetic Data Platform

A purpose-built synthetic data platform addresses the long-tail problem through three foundational pillars:

1. Precise Scenario Generation: From Probability to Certainty

Instead of hoping a rare event occurs, engineers can now define it parametrically. A micro-sleep is no longer a lucky capture; it is a configurable event with precise control over:

  • Eyelid Dynamics: Closure percentage, duration, and flutter frequency.
  • Head Pose: Nod angle, rotation, and the correlation between head droop and eyelid state.
  • Gaze Direction: The exact point of regard, simulating a “thousand-yard stare” distraction. This allows for the systematic creation of thousands of nuanced variations, filling the “coverage gap” with surgical precision.

2. Domain Randomization: Building Inherent Robustness

To ensure models perform reliably in any vehicle, under any condition, synthetic data platforms employ domain randomization. This involves systematically varying every element of the virtual scene:

  • Environmental: Lighting conditions (dawn glare, pitch night, tunnel entry), weather effects on windows.
  • Geometric: Vehicle interior models, seat positions, occupant demographics (age, height, physique).
  • Material & Sensor: Surface textures and sensor properties (e.g., IR reflectance of materials).

By training on this hyper-diverse, randomized data, the DMS model learns to focus on the core signal (e.g., eye state) and becomes invariant to irrelevant noise, achieving a level of robustness impossible with finite real-world datasets.

3. Inherently Perfect Ground Truth: The End of Annotation Ambiguity

Every pixel generated in a synthetic environment comes with perfect, pixel-level metadata. There is no human interpretation or disagreement.

  • A pixel belonging to an eyelid is automatically tagged with its precise, e.g., eye_state = 0.85_closed.
  • A child’s hand obscured by a blanket is still semantically segmented in the ground truth, even if invisible in the RGB image. This eliminates label noise, provides consistent data for training, and creates a definitive ground truth for validation, accelerating development cycles and increasing confidence in model performance.
A Foundation for Validation and Compliance

This engineered approach provides a controlled, repeatable, and fully auditable data pipeline. Scenarios can be generated at scale overnight and reproduced exactly for regression testing and to provide evidence for stringent regulatory submissions. This shifts DMS development from a reactive process, constrained by data scarcity, to a proactive one, driven by engineering requirements.

Case-in-Point: Validating a Euro NCAP 2026 + Child Presence Detection System

The theoretical “long-tail problem” becomes a matter of life and death in the context of Child Presence Detection (CPD). For an OEM pursuing Euro NCAP 2025+ compliance, a CPD system’s failure in a single, rare scenario, a child completely obscured by a blanket or hidden in a footwell, is unacceptable. Real-world testing alone cannot guarantee this level of robustness, creating a critical validation gap.

The Challenge: Incomplete Real-World Testing Undermines Confidence

An OEM’s prototype CPD system performs admirably in standard lab tests but reveals alarming vulnerabilities in edge cases. The model fails consistently when a child is:

  • Heavily Occluded: Partially covered by a blanket or hidden behind a seat.
  • Subject to Challenging Lighting: Washed out by direct glare or concealed in deep shadow.
  • In Unusual Poses: Curled up and motionless in a footwell or a rear-facing infant seat.

Physically and ethically capturing the thousands of variations of these safety-critical scenarios was a proven impossibility, putting both the Euro NCAP rating and, more importantly, child safety at risk.

The Synthetic Data Solution: Engineering a Comprehensive Virtual Proving Ground

To close this gap, the OEM turned to a synthetic data pipeline. The goal was not to replicate a dataset, but to engineer one that was more complete than any physically possible collection. They generated a wide, tailored dataset of over 100,000 virtual scenes, built on a foundation of parameterized control:

  • Scene Parameters: Systematically varying vehicle interiors, seat types, and material reflectivity.
  • Occupant Parameters: Defining a wide range of child ages, sizes, poses, and levels of occlusion (e.g., blanket coverage from 10% to 95%).
  • Environmental Parameters: Precisely controlling lighting conditions, from harsh midday sun to low-light IR illumination, to simulate sensor-specific challenges.

Crucially, every generated frame contained perfect, pixel-level ground truth (e.g., occlusion_level=0.75, child_visible=True), providing an unambiguous benchmark for training and validation.

The Outcome: Quantifiable Robustness and Accelerated Compliance

The impact of training and validating with this synthetic “edge-case universe” was transformative:

  • Performance Leap: The model’s recall on a held-out set of real-world edge cases increased by over 20 percentage points, drastically reducing dangerous false negatives.
  • Validation Velocity: The testing cycle was reduced from months to weeks, as every critical scenario could be generated and re-run on demand.
  • Demonstrable Safety: The OEM could now provide evidence-based validation to Euro NCAP, demonstrating systematic coverage of the long tail rather than relying on statistical chance.

This case proves that with synthetic data, the most critical scenarios are no longer the hardest to test; they become the most repeatable, measurable, and solvable.

The Anyverse Advantage: Building Trust in Synthetic Data for In-Cabin Monitoring Validation

For synthetic data to be the cornerstone of automotive safety validation, it must be more than just visually plausible; it must be physically and sensorically accurate. This is the critical differentiator for a platform like Anyverse InCabin. It moves beyond basic image synthesis to deliver a deterministic, sensor-accurate simulation environment that builds the trust required by OEM and Tier-1 safety engineers.

Sensor-Accurate Simulation: The Foundation for Real-World Performance

A robust DMS or CPD system often relies on a suite of sensors, RGB, IR, NIR, and sometimes ToF. The key to effective multi-sensor AI is understanding how these modalities interact with the physical world. The Anyverse InCabin platform generates perfectly synchronized data across all these sensors from the same virtual scene. It doesn’t just simulate what a camera sees; it models how infrared light reflects off skin and fabrics, how glare affects an RGB sensor, and how a Time-of-Flight sensor calculates depth. This ensures the AI is trained on a coherent, multi-faceted representation of reality, leading to models that perform reliably when deployed in physical vehicles.

Physics-Based Rendering: Beyond “Photorealistic” to “Physically Correct”

While “photorealism” is a common benchmark, it is insufficient for engineering. Anyverse InCabin is built on a physics-based rendering (PBR) engine that simulates the behavior of light, materials, and sensors according to physical laws. This means the pixel values in a generated image are not just artistically pleasing; they are an accurate representation of the radiance that a real sensor would capture. This physical accuracy is non-negotiable for building trust in the data and for developing algorithms that are sensitive to subtle cues, like the precise IR signature of a drowsy driver’s face or the reflectivity of a child seat buckle under varying light.

Scenario-Based Validation: A Virtual Proving Ground

The ultimate value of the platform is not just in generating data, but in enabling a rigorous validation workflow. With pre-built scenario libraries aligned with Euro NCAP protocols, engineers can move from data generation to systematic testing within a single environment. They can define a specific test, “validate CPD recall for a child 95% occluded by a blanket in a dark cabin with IR illumination”, and generate thousands of variations to stress-test the algorithm. This transforms the process from isolated data creation to an integrated, scenario-based virtual proving ground, dramatically accelerating the path to compliance.

Closing the Gap Between Laboratory and Road

This engineered approach to synthetic data, rooted in sensor accuracy, physical correctness, and scenario-based workflows, provides OEMs and Tier-1s with the missing tool needed to conquer the long tail. It shifts development from being constrained by data scarcity to being driven by safety requirements, ensuring that the rarest events on the road become the most tested scenarios in the lab.

Building Safer, More Robust DMS for the Road Ahead

The journey toward truly safe in-cabin monitoring systems culminates at the “long tail.” It is here, in the realm of rare driver behaviors and unforeseen occupant scenarios, that the final battle for robustness is fought. While high performance on common events is now a given, a system’s ultimate safety value, and its compliance with evolving standards like Euro NCAP, is determined by its resilience to these edge cases.

As we have explored, conquering this frontier with real-world data alone is a fundamental impossibility, constrained by ethics, cost, and physics. Synthetic data, specifically engineered with physical and sensor accuracy, is therefore not merely a useful tool in the developer’s kit; it is a fundamental enabler. It represents a paradigm shift from reactive data collection to proactive scenario engineering, allowing OEMs and Tier-1s to build and validate systems against a complete universe of possibilities, not just a statistically convenient sample.

Platforms like Anyverse InCabin are pivotal in this transition, providing the deterministic, trustworthy simulation environment needed to close the validation gap. They empower engineers to move with confidence, ensuring that the rarest events on the road become the most tested scenarios in the lab.

Looking ahead, as we progress toward higher levels of vehicle automation, the role of the interior sensor suite will only expand. The methodologies pioneered today for taming the DMS long tail will become the bedrock for validating the complex human-machine interactions of tomorrow. In this future, a leadership position in automotive safety will be intrinsically linked to a mastery of synthetic data, turning the industry’s greatest validation challenge into its most powerful assurance of safety and finally closing the DMS validation data gap.

Enjoyed this article?

Add us as a Preferred Source on Google to see more content like this in Discover and Top Stories.

About Anyverse

With over 25 years of heritage in physics-based simulation and a 2008 Academy Technical Achievement Award, Anyverse is a leading provider of high-fidelity synthetic data and validation tools for advanced Perception AI.

While Anyverse remains a premier partner for the Automotive market, specializing in In-Cabin Monitoring systems and ADAS, its technology is increasingly adopted across Defence, Robotics, and Industry 4.0. Leveraging a proprietary physics-grounded engine, procedural synthetic data generation, and next-gen Generative AI, Anyverse produces datasets with unmatched realism and sensor-level accuracy (including RGB, NIR, Radar, LiDAR, and Thermal).

Its unified validation framework helps partners ensure compliance with specific regulations like Euro NCAP, as well as broader safety standards for autonomous systems. By bridging the gap between simulation and reality, Anyverse accelerates development, reduces costs, and ensures trustworthy perception for vehicles, robots, and intelligent machines.

Solving the DMS Validation Data Gap: Synthetic Data to Master Rare Driver Behaviors

Solving the DMS Validation Data Gap Synthetic Data to Master Rare Driver Behaviors
SHARE

Table of Contents

Table of Contents

The DMS Accuracy Paradox

Modern driver monitoring systems (DMS) have achieved impressive accuracy rates, often exceeding 95% in detecting common distractions like yawning, phone use, or prolonged eye closure. However, this high benchmark performance masks a critical vulnerability: the DMS validation data gap. This is the chasm between laboratory performance and real-world safety, caused by the “long tail” of driver behavior—the rare, high-risk events that are nearly impossible to capture with real-world data.

This “DMS Accuracy Paradox” means a system can excel in testing yet fail on the road when faced with a brief micro-sleep, a moment of subtle cognitive distraction, or an edge case in child presence detection. While statistically infrequent, these failures carry disproportionate consequences for safety and brand integrity.

In Europe, driver distraction contributes to roughly 20–30% of crashes, highlighting the importance of capturing these rare behaviors. The regulatory landscape is now formalizing this challenge; with Euro NCAP 2026 and UNECE regulations expanding in-cabin monitoring requirements to include drowsiness, distraction, and child presence, the goalposts have moved. The new mandate is not just high accuracy, but comprehensive robustness.

OEMs need better data: controlled, repeatable, and physics-accurate.

This article explores how overcoming the DMS validation gap requires a new approach to data. We will examine how physics-based synthetic data provides the controlled, scalable, and semantically precise solution needed to engineer and validate DMS performance against these critical, rare scenarios, finally closing the gap between laboratory metrics and real-world safety.

The “Long Tail” Problem: Why Your DMS Is Only as Good as Its Rarest Test Case

In machine learning, the “long tail” refers to the vast set of rare events that are individually infrequent but collectively critical. For Driver Monitoring Systems (DMS), this is the domain of high-risk, low-frequency behaviors that are notoriously absent from real-world datasets. While a DMS might excel at detecting common distractions, its true safety value, and its ultimate regulatory validation, is determined by its performance on these rare but catastrophic scenarios.

Concrete Examples: Where State-of-the-Art DMS Stumble

Low-frequency driver and occupant states that carry disproportionate risk include:

Category

Examples

Challenge

Micro-sleeps

Eyelid flutter vs. 2–3 second closure

Difficult to capture naturally; ethically impossible to induce in real drivers

Subtle Distractions

Cognitive disengagement, mirror checks, gestures

Ambiguous, transient cues rarely labeled consistently

Child Presence Edge Cases

Partially visible children, occlusion under blankets, reflections on buckles

Safety-critical, ethically and practically impossible to capture in real-world data

The long tail manifests in several safety-critical categories where current data collection methods fall short:

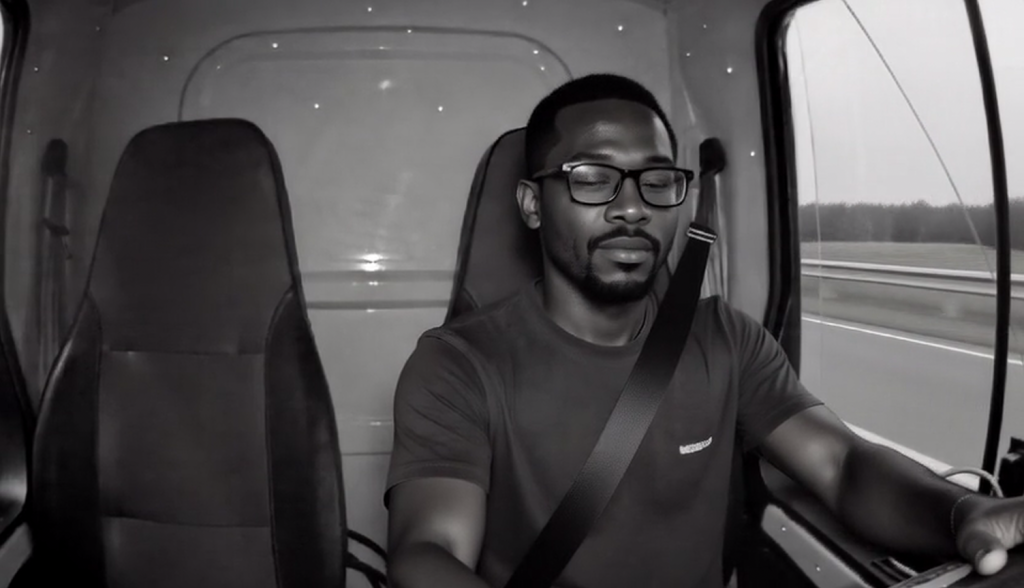
  • Micro-sleeps: The critical distinction between a long blink and a 2-3 second eyelid flutter is a matter of lane departure. Capturing thousands of natural, progressive micro-sleeps across diverse drivers, varied lighting, and fatigue levels is logistically infeasible and ethically prohibitive.

  • Subtle distractions: Distraction isn’t always a phone in hand. It can be cognitive “off-loading”, a driver staring blankly through the windshield, mentally disengaged. These ambiguous, transient states are nearly impossible to consistently capture and label from real-world video, creating a significant gap in understanding attentional loss.

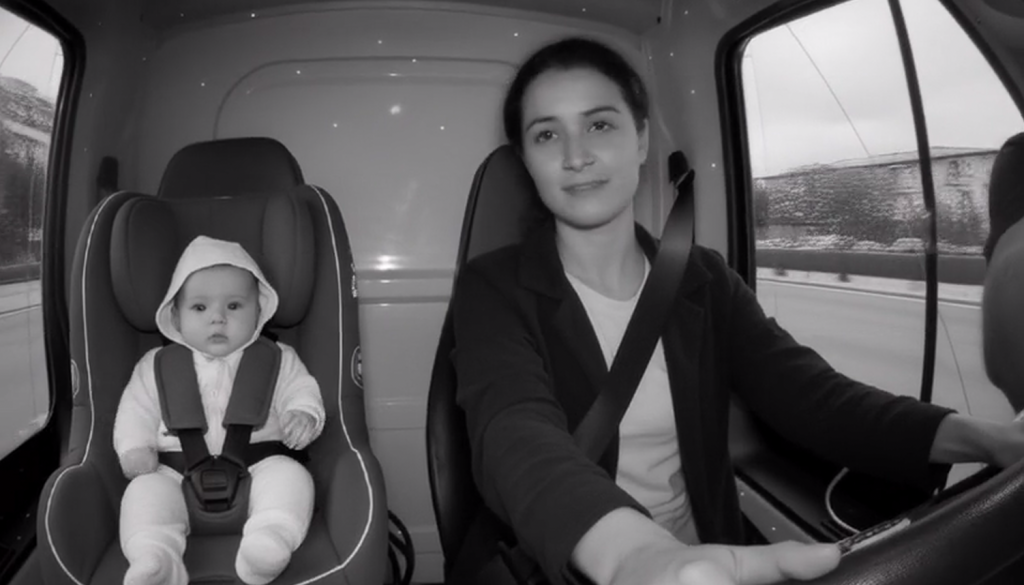
  • Child Presence Detection (CPD) edge cases: In CPD scenarios, the tolerance for error is zero. The system must identify a child partially obscured by a blanket, completely hidden behind a seat, or visible only as a reflection on a buckle. Artificially creating these scenarios for data collection with real children is both unsafe and unethical, leaving a dangerous void in training data, practically impossible.
The Insurmountable Hurdles of Real-World Data Collection

The common thread across all long-tail scenarios is the fundamental impossibility of capturing them at scale with real-world data. The challenges are not just logistical, but foundational:

  • Ethical & Safety Barriers: You cannot ethically induce drowsiness in test drivers or place children in potentially hazardous positions for the sake of data.

  • Combinatorial Explosion: Each scenario depends on a complex interplay of variables, driver age, posture, seat position, lighting (glare, IR reflectance), and behavioral context. Systematically replicating all these combinations in the physical world is prohibitively expensive and time-consuming.

  • Annotation Ambiguity: Even when rare events are captured, how do you consistently and accurately label a “subtle cognitive distraction”? Human annotators often disagree, leading to noisy, unreliable ground truth.

This creates the core paradox of DMS development: the most safety-critical data is, by its very nature, the most inaccessible. Relying solely on real-world data inevitably leaves a dangerous gap between benchmark performance and real-world robustness.

The Real-World Data Bottleneck: Why Physical Collection Fails the Long Tail

The long tail defines the frontier of DMS safety, yet it is a frontier that real-world data collection is fundamentally unequipped to explore. Relying solely on real-world data creates a bottleneck defined by four insurmountable constraints: scarcity, cost, ambiguity, and privacy. This makes validating robust DMS a major challenge, especially as Euro NCAP 2026 raises expectations for system performance.

Scarcity: You Can’t Schedule a Micro-Sleep

The very nature of long-tail events makes them elusive. Micro-sleeps, subtle cognitive distractions, and specific child presence edge cases are, by definition, rare and unpredictable. Systematically capturing a statistically significant volume of these events across the required variations of driver demographics, cabin configurations, and environmental conditions is a logistical impossibility. You cannot command a test driver to have a safety-critical lapse on cue. This scarcity creates a permanent coverage gap in datasets, leaving models untested against the very scenarios they are designed to prevent.
Cost: The Exorbitant Price of Rarity

Chasing rarity is prohibitively expensive. Establishing a data collection pipeline for in-cabin monitoring requires a fleet of instrumented vehicles, calibrated sensor suites (e.g., RGB, IR, NIR, Radar), and controlled test facilities. The cost multiplies exponentially when the goal is to capture thousands of hours of driving to find a few hundred critical seconds of rare events. Furthermore, the subsequent manual annotation of these complex behaviors adds a massive, ongoing expense, making comprehensive long-tail data collection a venture with a diminishing and untenable return on investment.

Annotation Ambiguity: The Subjectivity of Subtlety

Even when a rare event is captured, defining it is often subjective. How does one consistently label the precise moment a “blink” becomes a “micro-sleep”? Or quantify “cognitive distraction” from a driver’s vacant expression? Studies have shown inter-annotator disagreement rates of 12-15% in DMS behavioral datasets. This “label noise” directly injects uncertainty into model training, limiting the maximum achievable performance and making it difficult to validate systems against stringent safety benchmarks.

Privacy: Data Collection is Sensitive

In-cabin video is a minefield of personal data, encompassing biometric identifiers (facial features, gaze) and sensitive behaviors. This triggers strict global regulations like Europe’s GDPR, which mandates consent and anonymization, and UNECE R155, which covers cybersecurity. Collecting, storing, and processing this data at the scale required for the long tail introduces massive legal and reputational risk. The very act of comprehensive data collection becomes a compliance nightmare.

Engineering the Impossible: Generating the Long Tail with Synthetic Data

If real-world data collection is defined by its constraints, synthetic data generation is defined by its freedom. By moving from the physical to the virtual domain, we can engineer the very scenarios that are impossible to capture, with precision, scale, and control that transcends traditional methods. This is not merely supplementing real-world data; it is pioneering a new paradigm for DMS validation and future assessment.

The Core Capabilities of a Synthetic Data Platform

A purpose-built synthetic data platform addresses the long-tail problem through three foundational pillars:

1. Precise Scenario Generation: From Probability to Certainty

Instead of hoping a rare event occurs, engineers can now define it parametrically. A micro-sleep is no longer a lucky capture; it is a configurable event with precise control over:

  • Eyelid Dynamics: Closure percentage, duration, and flutter frequency.
  • Head Pose: Nod angle, rotation, and the correlation between head droop and eyelid state.
  • Gaze Direction: The exact point of regard, simulating a “thousand-yard stare” distraction. This allows for the systematic creation of thousands of nuanced variations, filling the “coverage gap” with surgical precision.

2. Domain Randomization: Building Inherent Robustness

To ensure models perform reliably in any vehicle, under any condition, synthetic data platforms employ domain randomization. This involves systematically varying every element of the virtual scene:

  • Environmental: Lighting conditions (dawn glare, pitch night, tunnel entry), weather effects on windows.
  • Geometric: Vehicle interior models, seat positions, occupant demographics (age, height, physique).
  • Material & Sensor: Surface textures and sensor properties (e.g., IR reflectance of materials).

By training on this hyper-diverse, randomized data, the DMS model learns to focus on the core signal (e.g., eye state) and becomes invariant to irrelevant noise, achieving a level of robustness impossible with finite real-world datasets.

3. Inherently Perfect Ground Truth: The End of Annotation Ambiguity

Every pixel generated in a synthetic environment comes with perfect, pixel-level metadata. There is no human interpretation or disagreement.

  • A pixel belonging to an eyelid is automatically tagged with its precise, e.g., eye_state = 0.85_closed.
  • A child’s hand obscured by a blanket is still semantically segmented in the ground truth, even if invisible in the RGB image. This eliminates label noise, provides consistent data for training, and creates a definitive ground truth for validation, accelerating development cycles and increasing confidence in model performance.
A Foundation for Validation and Compliance

This engineered approach provides a controlled, repeatable, and fully auditable data pipeline. Scenarios can be generated at scale overnight and reproduced exactly for regression testing and to provide evidence for stringent regulatory submissions. This shifts DMS development from a reactive process, constrained by data scarcity, to a proactive one, driven by engineering requirements.

Case-in-Point: Validating a Euro NCAP 2026 + Child Presence Detection System

The theoretical “long-tail problem” becomes a matter of life and death in the context of Child Presence Detection (CPD). For an OEM pursuing Euro NCAP 2025+ compliance, a CPD system’s failure in a single, rare scenario, a child completely obscured by a blanket or hidden in a footwell, is unacceptable. Real-world testing alone cannot guarantee this level of robustness, creating a critical validation gap.

The Challenge: Incomplete Real-World Testing Undermines Confidence

An OEM’s prototype CPD system performs admirably in standard lab tests but reveals alarming vulnerabilities in edge cases. The model fails consistently when a child is:

  • Heavily Occluded: Partially covered by a blanket or hidden behind a seat.
  • Subject to Challenging Lighting: Washed out by direct glare or concealed in deep shadow.
  • In Unusual Poses: Curled up and motionless in a footwell or a rear-facing infant seat.

Physically and ethically capturing the thousands of variations of these safety-critical scenarios was a proven impossibility, putting both the Euro NCAP rating and, more importantly, child safety at risk.

The Synthetic Data Solution: Engineering a Comprehensive Virtual Proving Ground

To close this gap, the OEM turned to a synthetic data pipeline. The goal was not to replicate a dataset, but to engineer one that was more complete than any physically possible collection. They generated a wide, tailored dataset of over 100,000 virtual scenes, built on a foundation of parameterized control:

  • Scene Parameters: Systematically varying vehicle interiors, seat types, and material reflectivity.
  • Occupant Parameters: Defining a wide range of child ages, sizes, poses, and levels of occlusion (e.g., blanket coverage from 10% to 95%).
  • Environmental Parameters: Precisely controlling lighting conditions, from harsh midday sun to low-light IR illumination, to simulate sensor-specific challenges.

Crucially, every generated frame contained perfect, pixel-level ground truth (e.g., occlusion_level=0.75, child_visible=True), providing an unambiguous benchmark for training and validation.

The Outcome: Quantifiable Robustness and Accelerated Compliance

The impact of training and validating with this synthetic “edge-case universe” was transformative:

  • Performance Leap: The model’s recall on a held-out set of real-world edge cases increased by over 20 percentage points, drastically reducing dangerous false negatives.
  • Validation Velocity: The testing cycle was reduced from months to weeks, as every critical scenario could be generated and re-run on demand.
  • Demonstrable Safety: The OEM could now provide evidence-based validation to Euro NCAP, demonstrating systematic coverage of the long tail rather than relying on statistical chance.

This case proves that with synthetic data, the most critical scenarios are no longer the hardest to test; they become the most repeatable, measurable, and solvable.

The Anyverse Advantage: Building Trust in Synthetic Data for In-Cabin Monitoring Validation

For synthetic data to be the cornerstone of automotive safety validation, it must be more than just visually plausible; it must be physically and sensorically accurate. This is the critical differentiator for a platform like Anyverse InCabin. It moves beyond basic image synthesis to deliver a deterministic, sensor-accurate simulation environment that builds the trust required by OEM and Tier-1 safety engineers.

Sensor-Accurate Simulation: The Foundation for Real-World Performance

A robust DMS or CPD system often relies on a suite of sensors, RGB, IR, NIR, and sometimes ToF. The key to effective multi-sensor AI is understanding how these modalities interact with the physical world. The Anyverse InCabin platform generates perfectly synchronized data across all these sensors from the same virtual scene. It doesn’t just simulate what a camera sees; it models how infrared light reflects off skin and fabrics, how glare affects an RGB sensor, and how a Time-of-Flight sensor calculates depth. This ensures the AI is trained on a coherent, multi-faceted representation of reality, leading to models that perform reliably when deployed in physical vehicles.

Physics-Based Rendering: Beyond “Photorealistic” to “Physically Correct”

While “photorealism” is a common benchmark, it is insufficient for engineering. Anyverse InCabin is built on a physics-based rendering (PBR) engine that simulates the behavior of light, materials, and sensors according to physical laws. This means the pixel values in a generated image are not just artistically pleasing; they are an accurate representation of the radiance that a real sensor would capture. This physical accuracy is non-negotiable for building trust in the data and for developing algorithms that are sensitive to subtle cues, like the precise IR signature of a drowsy driver’s face or the reflectivity of a child seat buckle under varying light.

Scenario-Based Validation: A Virtual Proving Ground

The ultimate value of the platform is not just in generating data, but in enabling a rigorous validation workflow. With pre-built scenario libraries aligned with Euro NCAP protocols, engineers can move from data generation to systematic testing within a single environment. They can define a specific test, “validate CPD recall for a child 95% occluded by a blanket in a dark cabin with IR illumination”, and generate thousands of variations to stress-test the algorithm. This transforms the process from isolated data creation to an integrated, scenario-based virtual proving ground, dramatically accelerating the path to compliance.

Closing the Gap Between Laboratory and Road

This engineered approach to synthetic data, rooted in sensor accuracy, physical correctness, and scenario-based workflows, provides OEMs and Tier-1s with the missing tool needed to conquer the long tail. It shifts development from being constrained by data scarcity to being driven by safety requirements, ensuring that the rarest events on the road become the most tested scenarios in the lab.

Building Safer, More Robust DMS for the Road Ahead

The journey toward truly safe in-cabin monitoring systems culminates at the “long tail.” It is here, in the realm of rare driver behaviors and unforeseen occupant scenarios, that the final battle for robustness is fought. While high performance on common events is now a given, a system’s ultimate safety value, and its compliance with evolving standards like Euro NCAP, is determined by its resilience to these edge cases.

As we have explored, conquering this frontier with real-world data alone is a fundamental impossibility, constrained by ethics, cost, and physics. Synthetic data, specifically engineered with physical and sensor accuracy, is therefore not merely a useful tool in the developer’s kit; it is a fundamental enabler. It represents a paradigm shift from reactive data collection to proactive scenario engineering, allowing OEMs and Tier-1s to build and validate systems against a complete universe of possibilities, not just a statistically convenient sample.

Platforms like Anyverse InCabin are pivotal in this transition, providing the deterministic, trustworthy simulation environment needed to close the validation gap. They empower engineers to move with confidence, ensuring that the rarest events on the road become the most tested scenarios in the lab.

Looking ahead, as we progress toward higher levels of vehicle automation, the role of the interior sensor suite will only expand. The methodologies pioneered today for taming the DMS long tail will become the bedrock for validating the complex human-machine interactions of tomorrow. In this future, a leadership position in automotive safety will be intrinsically linked to a mastery of synthetic data, turning the industry’s greatest validation challenge into its most powerful assurance of safety and finally closing the DMS validation data gap.


Enjoyed this article?

Tap to add us as a Preferred Source on Google to see more content like this.

About Anyverse

With over 25 years of heritage in physics-based simulation and a 2008 Academy Technical Achievement Award, Anyverse is a leading provider of high-fidelity synthetic data and validation tools for advanced Perception AI.

While Anyverse remains a premier partner for the Automotive market, specializing in In-Cabin Monitoring systems and ADAS, its technology is increasingly adopted across Defence, Robotics, and Industry 4.0. Leveraging a proprietary physics-grounded engine, procedural synthetic data generation, and next-gen Generative AI, Anyverse produces datasets with unmatched realism and sensor-level accuracy (including RGB, NIR, Radar, LiDAR, and Thermal).

Its unified validation framework helps partners ensure compliance with specific regulations like Euro NCAP, as well as broader safety standards for autonomous systems. By bridging the gap between simulation and reality, Anyverse accelerates development, reduces costs, and ensures trustworthy perception for vehicles, robots, and intelligent machines.